A business continuity plan on paper is worthless. True resilience is found by stress-testing the hidden points of failure that bring down even the most prepared UK firms during a real crisis.
- Critical dependencies, from single-supplier APIs to your own SSO-protected password manager, are your biggest undiscovered risks.
- Effective recovery isn’t about having backups; it’s about having air-gapped, insurer-approved recovery plans you can execute in under 4 hours.
Recommendation: Stop updating the document. Start running « fire drills » on your live systems and auditing your entire supply chain for cascading fragility.
The question is no longer *if* a digital disaster will strike your UK operations, but *when*. Whether it’s a ransomware attack, a critical supplier outage, or a catastrophic server failure, the moment of truth arrives. You reach for your Business Continuity Plan (BCP)—the meticulously crafted document meant to be your playbook for survival. But in too many boardrooms, there is a dangerous assumption: that the plan itself is the defence. It is not. Most BCPs are exercises in theoretical planning, filled with untested assumptions and silent vulnerabilities that only reveal themselves in the chaos of a real-world outage.
Standard advice tells you to define recovery objectives and back up your data. This is basic hygiene, not a strategy. The real work of resilience lies in uncovering the non-obvious points of failure. It’s about questioning the very tools you rely on for recovery and understanding the cascading impact of a single weak link in your supply chain. It’s about moving beyond the idea of passive recovery and embracing a culture of active resilience, where your systems are continuously tested against the certainty of failure.
This isn’t another guide to writing a BCP. This is an audit of the critical failure points that most plans overlook. We will dissect the fragile assumptions holding your strategy together and provide battle-hardened frameworks to replace them. We will move from theoretical RTOs to the brutal financial reality of downtime, from checklist-based tests to live-fire drills, and from hoping for the best to preparing for the worst. The goal is simple: to forge a plan that doesn’t just exist on a server, but one that executes flawlessly when the lights go out.
This article provides a strategic breakdown of the core components of a truly effective continuity plan. The following summary outlines the key areas we will explore to build genuine operational resilience.
Summary: Key Pillars of a Resilient Business Continuity Plan
- Why Your « Recovery Time Objective » Must Be Under 4 Hours for Critical Apps?
- How to Run a « Fire Drill » for Your Servers Without Disrupting Business?
- Cloud Backup or Tape: Is Physical Media Still Relevant for Ransomware Protection?
- The Password Manager Mistake That Locks Companies Out During a Crisis
- When to Tell Customers About an Outage: Immediate vs Verified Communication
- The Single-Supplier Risk That Could Halt Your Production Line for Weeks
- How to Create a Ransomware Recovery Plan That Satisfies Insurers?
- Why Cyber-Resilience Is Your Best Defence Against Ransomware in the UK?
Why Your « Recovery Time Objective » Must Be Under 4 Hours for Critical Apps?
A Recovery Time Objective (RTO) is not an arbitrary KPI; it is a direct calculation of your business’s pain threshold. For any critical application—be it your e-commerce platform, payment gateway, or core ERP system—every minute of downtime translates into tangible financial loss, operational paralysis, and eroding customer trust. The four-hour mark is often the tipping point where the damage becomes exponential. Beyond this window, reputational harm solidifies, service-level agreements (SLAs) are breached, and the cost of recovery skyrockets. The $4.88 million average cost per incident, as detailed in IBM’s 2024 Cost of a Data Breach Report, is not just from the breach itself but from the prolonged business interruption that follows.
Consider a typical e-commerce company reliant on its website for all sales. A server failure during a peak sales period triggers its disaster recovery plan. Because the company had a strictly defined RTO of four hours, it had already invested in automated backup restoration and failover systems. Within three hours, the site was restored, limiting the financial bleeding. Had their RTO been a vague « as soon as possible, » the uncoordinated scramble could have easily stretched into a full day of lost revenue and permanently churned customers.
Calculating the true cost of downtime goes beyond lost revenue per hour. You must factor in the cascading costs: penalties for breached SLAs, the salaries of idle employees whose work depends on the downed system, the cost to re-acquire customers who leave for a competitor, and the long-term, unquantifiable damage to your brand’s reputation. When you map these escalating costs against time, the necessity of a sub-four-hour RTO for your most critical functions becomes brutally clear. It is the line between a manageable incident and a corporate crisis.
How to Run a « Fire Drill » for Your Servers Without Disrupting Business?
The most dangerous assumption in business continuity is that a plan, untested in a live environment, will work under pressure. A « tabletop exercise » where you talk through a scenario is a good start, but it doesn’t replicate the technical and human stress of a real failure. The gold standard for testing is the « fire drill » for your servers—a controlled injection of failure to see how your systems and teams react. This practice, known as Chaos Engineering, isn’t about recklessly breaking things; it’s about methodically exposing weaknesses before an attacker or an accident does.
Leading technology firms have moved beyond theoretical drills. A prime example is Capital One, which integrated Chaos Engineering directly into its development pipeline. They deliberately terminate live instances of new microservices under a controlled load test to validate that the system remains stable and performant with reduced capacity. This proactive approach of continuous validation ensures that resilience is built-in, not bolted on. It answers the critical question: « Will our failover systems actually fail over? »
For most UK firms, a practical starting point is a Blue/Green deployment strategy. This involves running two identical production environments— »Blue » (the current live version) and « Green » (the new version). You can safely run your fire drill on the Green environment with a small percentage of live traffic. By configuring your load balancer to switch traffic, you can simulate a failure and test your recovery procedures, monitoring key metrics in real-time. If anything goes wrong, you can switch back to the stable Blue environment with a single click, ensuring zero disruption to the business. This method provides a safe, controlled arena to turn theory into proven capability.
Action Plan: Implementing a Blue/Green Deployment Test
- Set up identical production (Blue) and staging (Green) environments.
- Configure your load balancer with the capability to switch traffic between the two environments instantly.
- Implement comprehensive, automated health checks that continuously monitor the performance of both environments.
- Create and document rollback procedures that can be executed with a single click in case of failure.
- Begin testing by directing a small fraction of live traffic (5-10%) to the Green environment to validate its stability.
Cloud Backup or Tape: Is Physical Media Still Relevant for Ransomware Protection?
In an era dominated by cloud-first strategies, magnetic tape can seem like a relic. Yet, for the specific, existential threat of ransomware, its « obsolescence » is its greatest strength. Modern ransomware is designed to be insidious; it moves laterally across your network, actively seeking out and encrypting connected backups, including those in the cloud. If your cloud backup repository is connected to your primary network for easy access, it’s a target. This creates a terrifying scenario where both your live data and its « safe » copy are compromised simultaneously.
This is where the concept of the « air gap » becomes your most powerful weapon. An air gap is a physical and electronic separation between your network and your backup data. Tape backups, by their very nature, create a perfect air gap. Once a tape is written and removed from the drive, it is offline and immunologically isolated from any network-based attack. No ransomware variant can traverse a physical space to infect a tape stored in a secure, off-site vault. This makes it the ultimate « undo » button in a worst-case scenario.
The best practice for data protection remains the 3-2-1 rule: maintain at least three copies of your data, on two different types of media, with one copy stored off-site. A modern, resilient strategy combines the speed and convenience of cloud backups for rapid operational recovery (addressing your RTO) with the immutable security of air-gapped tape backups for catastrophic disaster recovery. The cloud handles the frequent, smaller incidents, while tape provides the last line of defence that ensures your business can be rebuilt from scratch, even if your entire digital infrastructure is reduced to encrypted rubble. For a risk manager, ignoring this physical fail-safe is a gamble you cannot afford to take.
The Password Manager Mistake That Locks Companies Out During a Crisis
In a crisis, access is everything. Your team needs to get into cloud consoles, recovery tools, and communication platforms. You wisely use a password manager to secure these credentials. But here lies a critical, often-overlooked single point of failure: protecting your password manager with the same Single Sign-On (SSO) system that might be the source of the outage. If your primary identity provider (like Azure AD or Okta) goes down, your entire recovery toolchain, starting with the very vault containing the keys to fix the problem, becomes inaccessible. You are locked out of your own lifeboat.
The critical mistake is protecting your password manager with the same Single Sign-On that is the source of the outage. If your SSO is down, your entire recovery toolchain, starting with the password manager, is inaccessible.
– Security Architecture Expert, Enterprise Security Best Practices Guide
This dependency creates a catastrophic cascading fragility. To mitigate it, you must establish a « break-glass » emergency access protocol that is completely independent of your daily operational systems. This isn’t just a backup password; it’s a documented, tested procedure for authenticating key personnel when all primary systems have failed. It relies on physical tokens and out-of-band methods that cannot be compromised by the ongoing digital crisis.
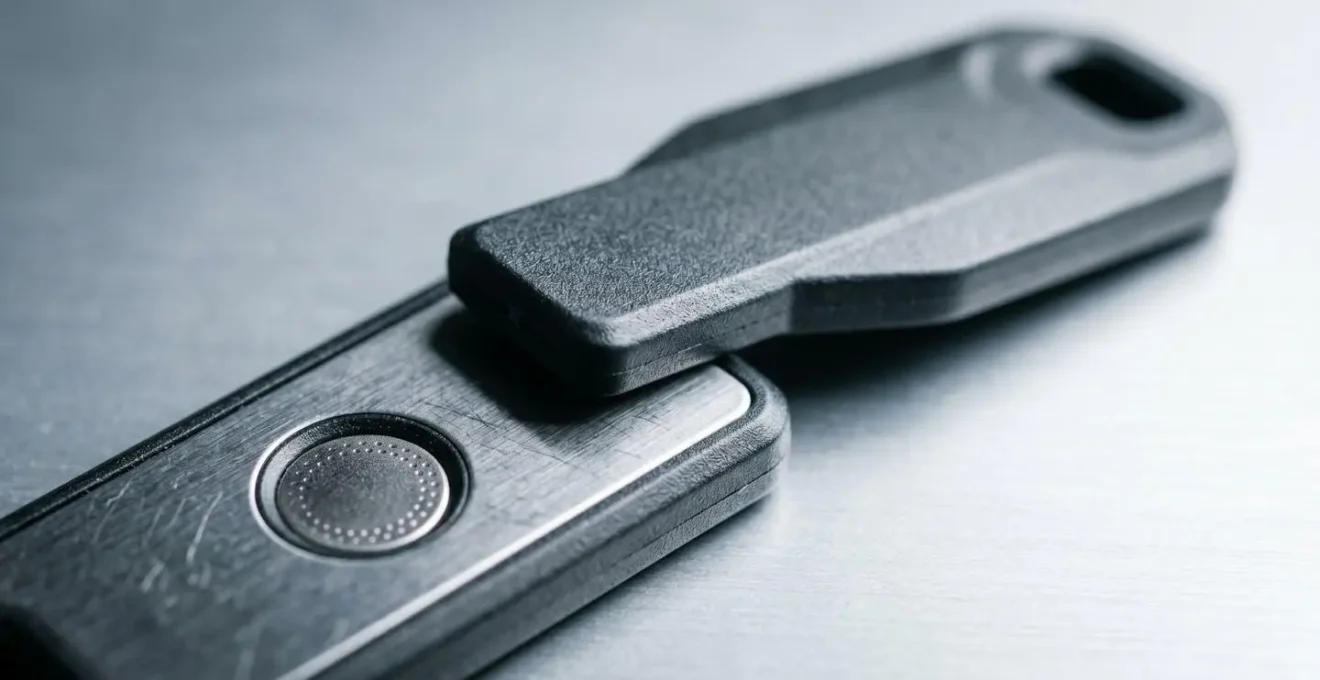
A robust break-glass protocol includes several layers. Master recovery credentials should be stored in a physical safe, requiring dual custody for access. Authentication should mandate the use of separate, hardware-based security keys (like YubiKeys) held by designated C-level executives. The entire procedure, from accessing the safe to recovering the first critical system, must be documented in a printed runbook stored with the credentials. This protocol is your ultimate fail-safe, ensuring that even in a total SSO meltdown, a trusted few can regain control and begin the recovery process.
When to Tell Customers About an Outage: Immediate vs Verified Communication
During an outage, you fight a war on two fronts: the technical battle to restore service, and the public relations battle to maintain customer trust. The instinct can be to stay silent until you have a solution, fearing that an early admission of a problem will cause panic. This is a mistake. In the age of social media, silence is not golden; it’s a vacuum that will be filled with customer speculation, frustration, and anger. A proactive, transparent communication strategy is essential to managing the narrative.
The most effective approach is the Acknowledge, Inform, Update (AIU) framework. This structured cadence turns a communication crisis into a managed process.
- Acknowledge: Within minutes of confirming a major incident, post an initial, brief message on your status page and social channels. It doesn’t need details. It just needs to say, « We are aware of an issue affecting [service] and are actively investigating. We will provide another update in 30 minutes. » This immediately shows you are in control.
- Inform: Once you have verified technical details, provide a clear, non-jargonistic explanation of what is happening and which services are impacted. Avoid blame or speculation. Stick to the facts.
- Update: Maintain a regular update cadence (e.g., every 30 minutes), even if the update is « We are still working on the problem. » This regular contact prevents customers from feeling abandoned and demonstrates that the issue is a top priority.
This strategy is only possible if your recovery plan is efficient. As research from the Disaster Recovery Institute International shows, organisations with documented and tested RTO targets achieve a 60% faster recovery. This speed gives your communication team the confidence to be transparent, knowing that the technical team is executing a well-rehearsed plan. The faster you recover, the more credibility your communications have.
The Single-Supplier Risk That Could Halt Your Production Line for Weeks
Your operational resilience is only as strong as the weakest link in your supply chain. In a digitally integrated world, a critical single point of failure often lies outside your own walls, with a third-party supplier. A payment gateway API, a specialist software provider, or a core logistics partner can become the epicentre of a crisis that you are powerless to fix directly. An e-commerce store, for example, can face a complete shutdown if its sole payment API provider goes down, creating an immediate and catastrophic loss of revenue and reputation.
The problem is that risk is not confined to your direct (Tier 1) suppliers. A Tier 2 risk—a failure at your supplier’s supplier—can be just as devastating. If your SaaS CRM provider’s cloud host (e.g., a specific AWS region) suffers a major outage, your business is impacted. This cascading fragility extends down through multiple tiers, creating a complex web of dependencies that must be mapped and understood. As a risk manager, you must look beyond your immediate contractual relationships and assess the entire ecosystem your business relies on.
A structured N-Tier Supplier Risk Assessment is not a « nice-to-have »; it is a fundamental pillar of a modern BCP. This process involves identifying critical suppliers at every tier, understanding their own continuity plans, and demanding contractual obligations for resilience, such as multi-region deployments or geographic diversification. The following matrix provides a framework for this analysis.
| Tier Level | Risk Type | Example | Mitigation Strategy |
|---|---|---|---|
| Tier 1 | Direct Supplier | Primary SaaS CRM | Contractual SLAs with penalties |
| Tier 2 | Supplier’s Infrastructure | CRM’s cloud provider (AWS/Azure) | Multi-region deployment requirements |
| Tier 3 | Supplier’s Dependencies | CRM’s payment processor | Escrow agreements for source code |
| Tier 4 | Geographic Concentration | All suppliers in same region | Mandatory geographic diversification |
How to Create a Ransomware Recovery Plan That Satisfies Insurers?
In the UK, having a cyber insurance policy is no longer a guarantee of a payout after a ransomware attack. Insurers, hit by escalating costs, have become far more stringent. They now demand proof of robust, pre-emptive controls and a tested recovery plan before they will even consider a claim. A generic BCP is not enough; you need a specific, auditable ransomware recovery plan that demonstrates you have taken every reasonable step to prevent and contain an attack.
Your insurer will want to see a defence-in-depth strategy. This starts with preventative controls. They will audit your endpoint protection, demanding Endpoint Detection and Response (EDR) solutions on 100% of devices, not just basic antivirus. They will scrutinise your network architecture, looking for micro-segmentation that prevents an attacker from moving laterally from a compromised laptop to a critical server. And crucially, they will demand evidence of immutable, air-gapped backups. You must be able to prove, with auditable logs, that you have regularly tested restoring from these backups.
Beyond technology, insurers now mandate process and governance. They expect to see:
- Regular Phishing Simulations: Documented monthly tests with high pass rates to demonstrate employee vigilance.
- Quarterly Tabletop Exercises: Proof that your executive team, including legal counsel, has walked through a ransomware scenario and knows the decision-making process.
- A Pre-Approved Ransom Decision Committee: A formal body that is authorised to make the difficult « pay or not pay » decision, guided by legal and forensic experts.
Failing to meet these criteria gives your insurer a clear reason to deny your claim, leaving you to face the full, catastrophic cost of the attack alone. Your ransomware recovery plan is now as much a financial compliance document as it is a technical one.
Key Takeaways
- A sub-4-hour RTO is not a target but a financial necessity for critical applications to prevent exponential damage.
- Real-world « fire drills » using Chaos Engineering or Blue/Green deployments are the only way to validate that your recovery plan actually works.
- Single points of failure are often hidden in your recovery toolchain (like SSO-protected password managers) and external supply chain, requiring specific, independent protocols.
Why Cyber-Resilience Is Your Best Defence Against Ransomware in the UK?
The traditional approach to disaster recovery is reactive. It focuses on restoring systems after they have failed. While necessary, this mindset is insufficient for the persistent, evolving threat of ransomware. A more powerful paradigm is cyber-resilience, a proactive and holistic strategy that assumes compromise is inevitable and designs the entire business—people, processes, and technology—to withstand, contain, and rapidly recover from an attack.
Every business should have the mindset that they will face a disaster, and every business needs a plan to address the different potential scenarios
– Goh Ser Yoong, Head of Compliance at Advance.AI
For UK firms operating under the scrutiny of regulators like the PRA and FCA, cyber-resilience is becoming a mandatory posture. It moves beyond a simple BCP document to become a living, breathing part of the corporate culture. It means investing in preventative measures like network segmentation and EDR not as a cost, but as an enabler of business continuity. It means empowering employees through continuous training to be the first line of defence. As demonstrated by financial institutions like JPMorgan Chase, a robust resilience framework allows even the most critical systems to recover within predetermined windows, preventing systemic shocks.
Ultimately, a ransomware recovery plan is just one component of a cyber-resilient strategy. Resilience is the ability to absorb a blow and continue to function. It’s the secure, air-gapped backup that allows you to restore your data without paying a ransom. It’s the well-rehearsed communication plan that retains customer trust during the outage. It is the culture of preparedness that allows your team to execute flawlessly under extreme pressure. For a COO or Risk Manager in the UK, building this resilience is not just the best defence; it is the only viable path to long-term survival in an increasingly hostile digital landscape.
Now is the time to move from planning to action. Use this framework to conduct a rigorous audit of your existing Business Continuity Plan, hunt for these hidden vulnerabilities, and build a system that delivers true resilience when it matters most.